AI agent evaluation

Your AI agent sounds just as confident when it is wrong.

Kayzn is an AI agent evaluation consultancy. We turn expert judgement into measurable criteria, and keep score as your AI agents evolve.

You build the AI agent, we evaluate it. We cover the evaluation process end to end: we audit what you have, we design what is missing, we build it, and we teach your team to run it.

Elias HarounShehaaz SaifBoth partners, on every engagement.
One request, end to end

Step 1A customer asks

“Was I charged twice for my August payment?”

One real request, out of thousands.

Step 2Your agent looks things up

Was I charged twice for my August payment?

Payment history · AugDuplicate-charge policy v4Refund terms §7

It pulls what it thinks it needs.

Step 3It answers

“Yes — a duplicate charge on 14 August was already refunded on 19 August.”cites Payment history · Aug

Confident, and it sounds right.

Step 4Kayzn checks it

Backed by what it actually looked up

Points at the right document

Used the current policy, not last year's

Answered the whole question left out what happens next

Four checks your own experts wrote.

Step 5What we found

One answer is not the point. This is the pattern behind it.

8.4 / 10

answers meet your team's definition of correctand now you can see the 1.6 that do not

Leaves out what happens next14%

Right document, wrong paragraph6%

Answers from a superseded policy3%

The same failure, counted across every trace you sent.

Step 6What you get

A straight answer about your agent, before you ship it or while it is already live.

Ready to ship for four of your five question types. Not for refunds.

  • 8.4 / 10answers meet your written standard
  • 2 fixesto make first, in priority order
  • Every weekre-checked as your agent changes

We do not build your agent. We tell you where it stands, in a sentence you can repeat — and what to fix first.

01 / What we take on

Four situations we are usually called into.

These are the ones we see most often. If your situation looks different, we would still like to hear about it.

01

A definition of correct that lives in a document

TodaySomeone wrote down what good looks like. It is a page in a wiki, and the release still turns on whoever read thirty samples that morning.

With KayznBuilt and running in your own pipeline. The automated judge, the model doing the scoring, is measured against your experts before it can block anything. Your team logs into a running view of how often it agrees.
02

Evals that pass, and a failure your customer found first

TodayThe suite is green. The thing that broke was not in it, and nobody knows what else is not in it.

With KayznA catalogue of the ways it actually fails, read out of your own traces. Those are the record of what your AI agent did and what it had in front of it. Then the criteria, the scoring guide and the labelled examples that would have caught it.

03

An AI agent in production that nobody quite trusts

TodayIt is live, it is useful, and no one can tell you how often it is right or what it does when it is wrong.

With KayznWe read what it actually did, score it against a written definition of correct, and tell you the error rate of our own finding as well as the agent's.

04

One person is the only one who can say whether an answer is right

TodayThe labelling, the criteria and the re-checking all sit with them, and the hosted model changes underneath you anyway.

With KayznYour team trained to run the labelling, maintain the criteria and re-calibrate when the model moves, so it is yours to do.

Written for your industryFinancial servicesHealthcareInsuranceLegal

02 / Selected work

What the work actually produced.

What we measured, what it changed, and the numbers to show it, including the part that is not good enough yet.

69%→0%
Judge to human agreement
9.9%→0%
False positives
20.9%→0%
False negatives

A financial services firm's AI platform team worked with Kayzn on one Evaluation System Build. Each run is compared against prior results, criterion by criterion, so a regression surfaces before release. The judge's agreement with human labelers reached 77%, short of the 85% bar Kayzn set before it would let a criterion block a release without a person checking.

What the gate reports on a buildIllustrative
GroundednessRequiredPass
Citation correctnessRequiredPass
Retrieval relevanceRequiredPass
CompletenessRequiredFail
RecencyOptionalPass

Release held one required dimension failed

A prompt passes only if every dimension marked required for that question passes, so one failure holds the release regardless of the others: a gate, not an average.

All case studies →

03 / Team

Both partners, on every engagement.

The name comes from kaizen, Japanese for change for the better: small steady steps rather than one big push. Evaluation works the same way. You do not settle trust once and move on, you measure one criterion, improve what the number shows you, and measure it again.

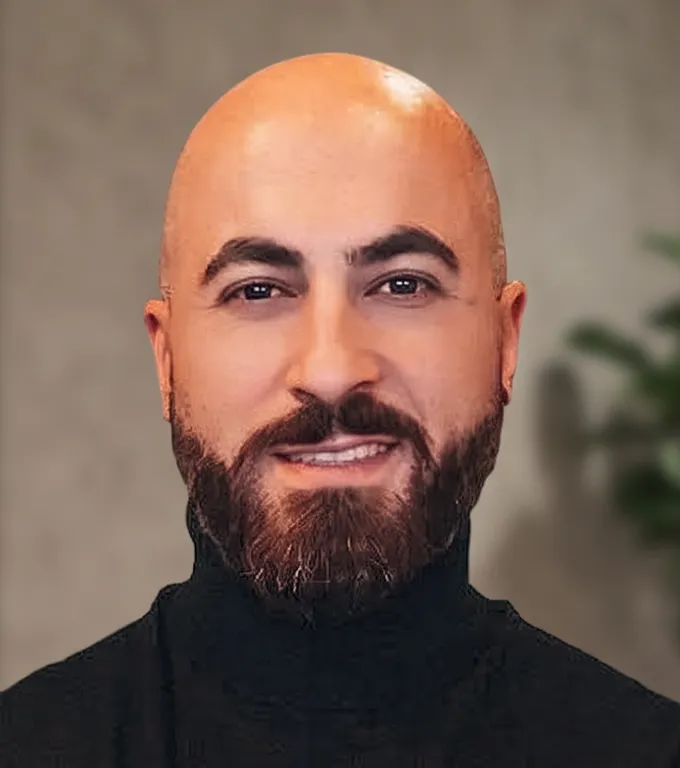
Elias Haroun

Elias Haroun

Partner · Los Angeles

Senior engineer and tech lead at Amazon, with over a decade across full-stack, cloud, MLOps, and DevOps. He has led technical teams and mentored hundreds of developers, from bootcamp graduates to senior engineers. He has built agentic systems and RAG pipelines himself, which is where he learned how quietly they fail, and that experience now points at one thing: the criteria, the calibration of the judge, and the gate that decides whether a release ships.

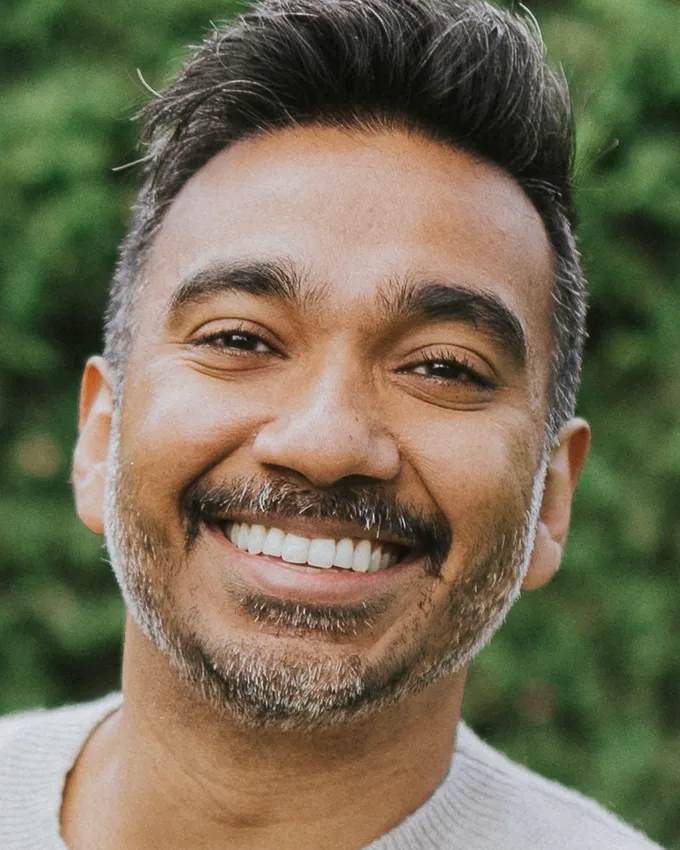
Shehaaz Saif

Shehaaz Saif

Partner · Montréal

A product and technology leader with a decade at Expedia Group. Seven years engineering the systems behind hotel pricing and recommendations, then leading the AI evaluation and quality frameworks that put AI-driven travel in front of millions of travellers. He has set the quality bar AI had to clear before it reached a customer, and been the person accountable for the number behind it.

04 / Services

Six ways in. Start with a conversation.

Every step ends with something you keep. What you keep is a running view of how often your AI agents are right, and it keeps updating.

Still deciding what to measure

You know the AI agent needs evaluation, but you do not yet have a written definition of what makes an answer correct.1 way in
01Evaluation Fit CallOur honest read on whether an evaluation is worth running on this AI agent, and what it would and would not establish.Free

Running, and you need to know how often it's right

Your AI agent is live and producing traces, and you need to measure how often it's actually right.2 ways in
02Trace ReviewA run against traces your AI agent has already produced, in a view you log into, with criteria drawn from the failures we actually find in them.Free
03Evaluation Readiness AuditWhat you can and cannot currently measure, a first criteria set drafted from your own traces, and agreement numbers on a first pass.

Need evaluation built into operations

You need evaluation running in your pipeline or on a schedule, not as a one-time run.3 ways in
04Calibrated Release Gate PilotOne AI agent, one calibrated gate, live in your pipeline, with the judge measured against your experts before it decides anything, reporting into a dashboard your team logs into.
05Evaluation System BuildThe engine your other teams can adopt by configuration rather than by fork, wired into CI, with a runbook for whoever operates it.
06Continuous Quality GateThe same criteria re-run on a schedule, re-calibrated against fresh human labels when the model moves underneath you.Ongoing

What each one includes →

05 / Blog

What we learn, written down.

What we have learned doing this work, explained plainly. Take what is useful.

Start with a conversation

Book an Evaluation Fit Call.

Free, and useful whether or not we work together. Bring one AI agent at any stage, from an early design to production. We will tell you honestly what can be evaluated now, what has to exist first, and what an evaluation would and would not establish.

Not ready for a call? Send us the one criterion you trust least and we will write back on what it would take to make it decide something.

Pick a time →

No deck. No discovery workshop. One AI agent, what it does or is meant to do, and a partner on the call.